See your product through something that just used it for the first time.
Every screen the agent reached is read back three ways: is it usable, is it crafted, does it agree with the screens either side of it. It runs on the phone and in the browser, so the same journey can be judged where your customers actually are. Every finding points at the frame it came from.
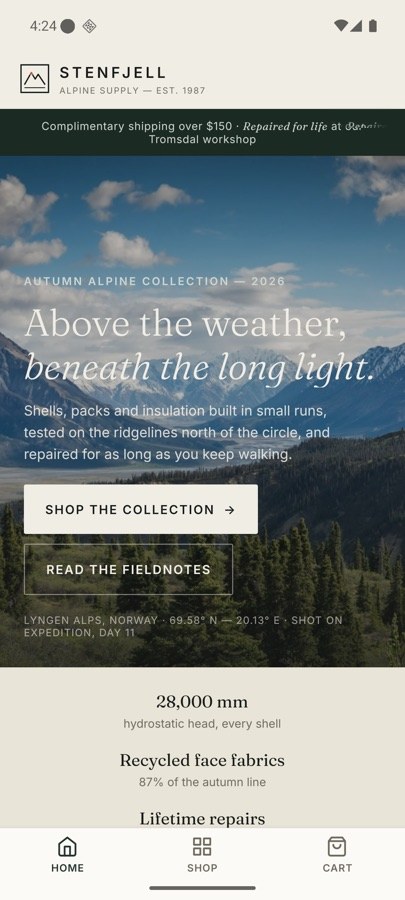
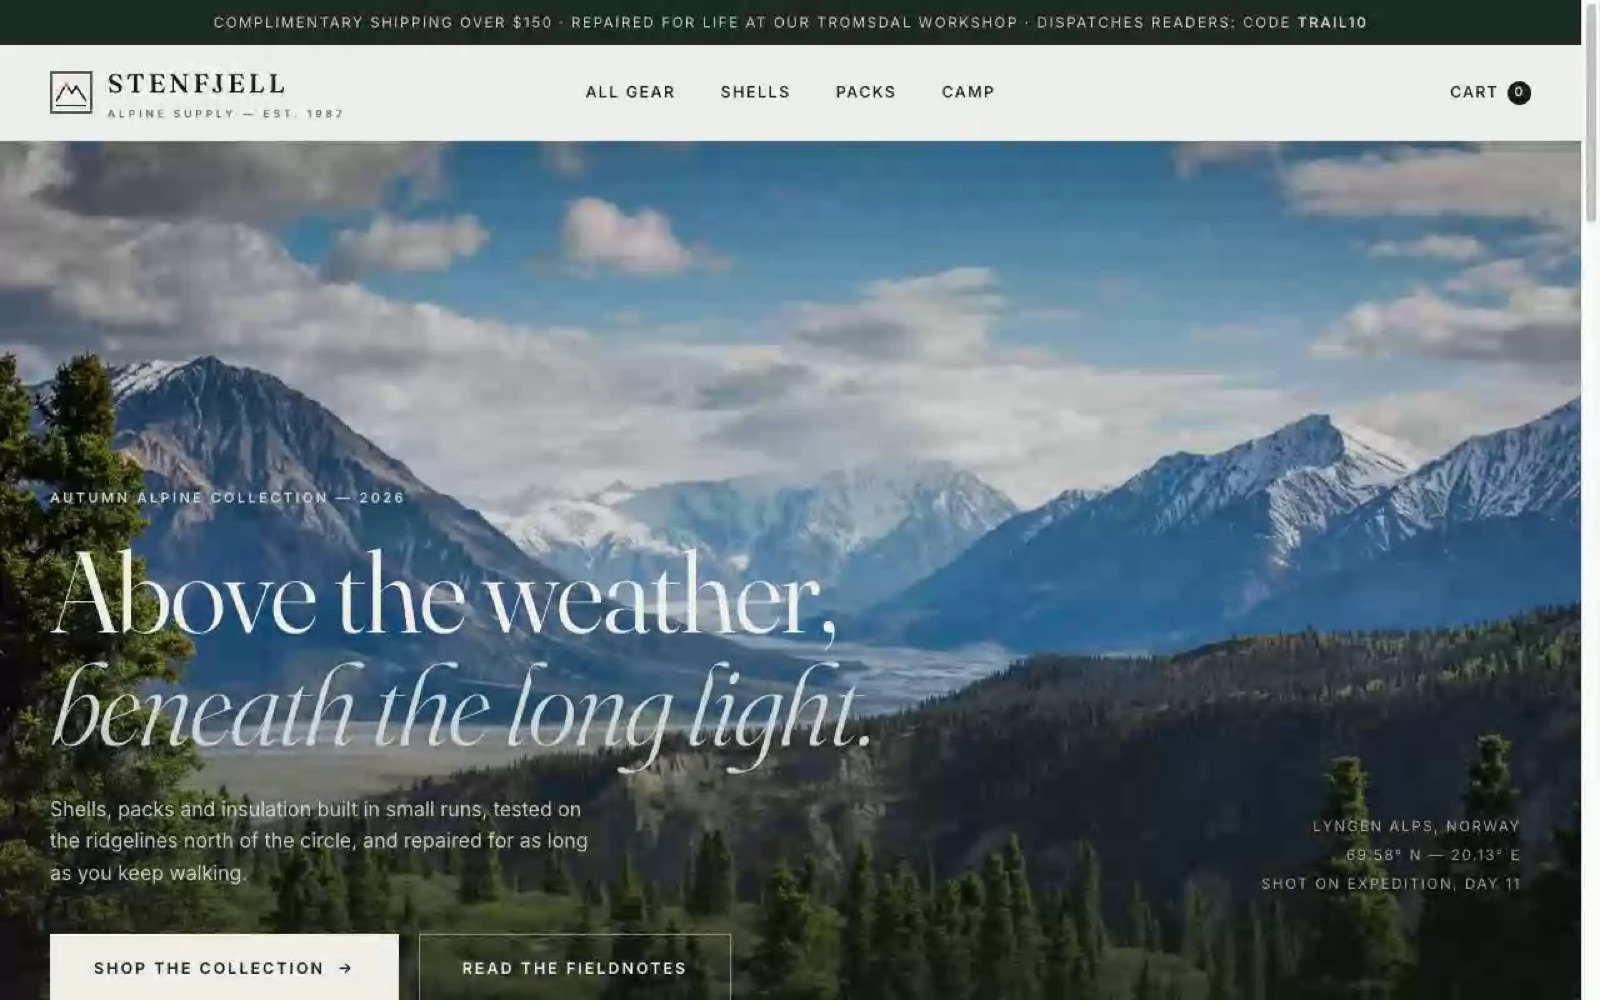
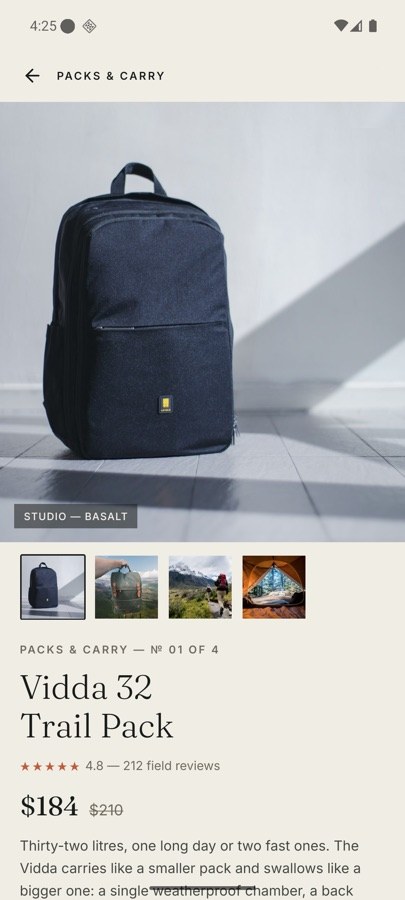
Opened one pack and looked for the way to buy it
Four things you get from one run
Three readings of one journey
Usability, visual craft, and consistency across the flow. Three different questions asked of the same evidence, so a finding is never only a matter of taste.
The phone and the browser
The same journey read on both, which is the only way to catch the screen that was designed once and adapted badly.
The frame it came from
Every finding carries the screen it was read from and the step it happened on. You can disagree with the agent while looking at exactly what it looked at.
What is done well, too
A report that only lists faults cannot be trusted about their weight, so the things the app gets right are named in the same voice.
Four terms do most of the work. None of them are ours to redefine in a meeting later.
The three readings
Usability asks whether a person could do it. Visual craft asks whether the screen was built with care. Flow consistency asks whether the screens agree with each other.
Contact sheet
The ordered set of screens a run actually reached, which is what gets read. Nothing is judged that the agent did not see.
Deep read
The second pass over the worst screens at full resolution, where the small things live.
Friction
Effort the app charged the person while working exactly as built. Searches that returned nothing, dead ends, repeated taps, replanning loops, recovery detours.
Three readings, one pass
Usability, visual craft and consistency across the flow. Three different questions asked of the same evidence, so a finding is never just an opinion about taste.
Both surfaces, one vocabulary
The phone run and the browser run are read the same way, so "worse on mobile" is a thing the report can actually say instead of a thing you argue about.
Evidence, not adjectives
Every finding carries the screenshot it was read from and the step it happened on. You can disagree with the agent while looking at the same frame it looked at.
Ranked, so you can stop reading
The screens are ordered by how much they cost the user, and only the worst get the expensive second read at full resolution.